Defining Pearson Correlation on
Motivation
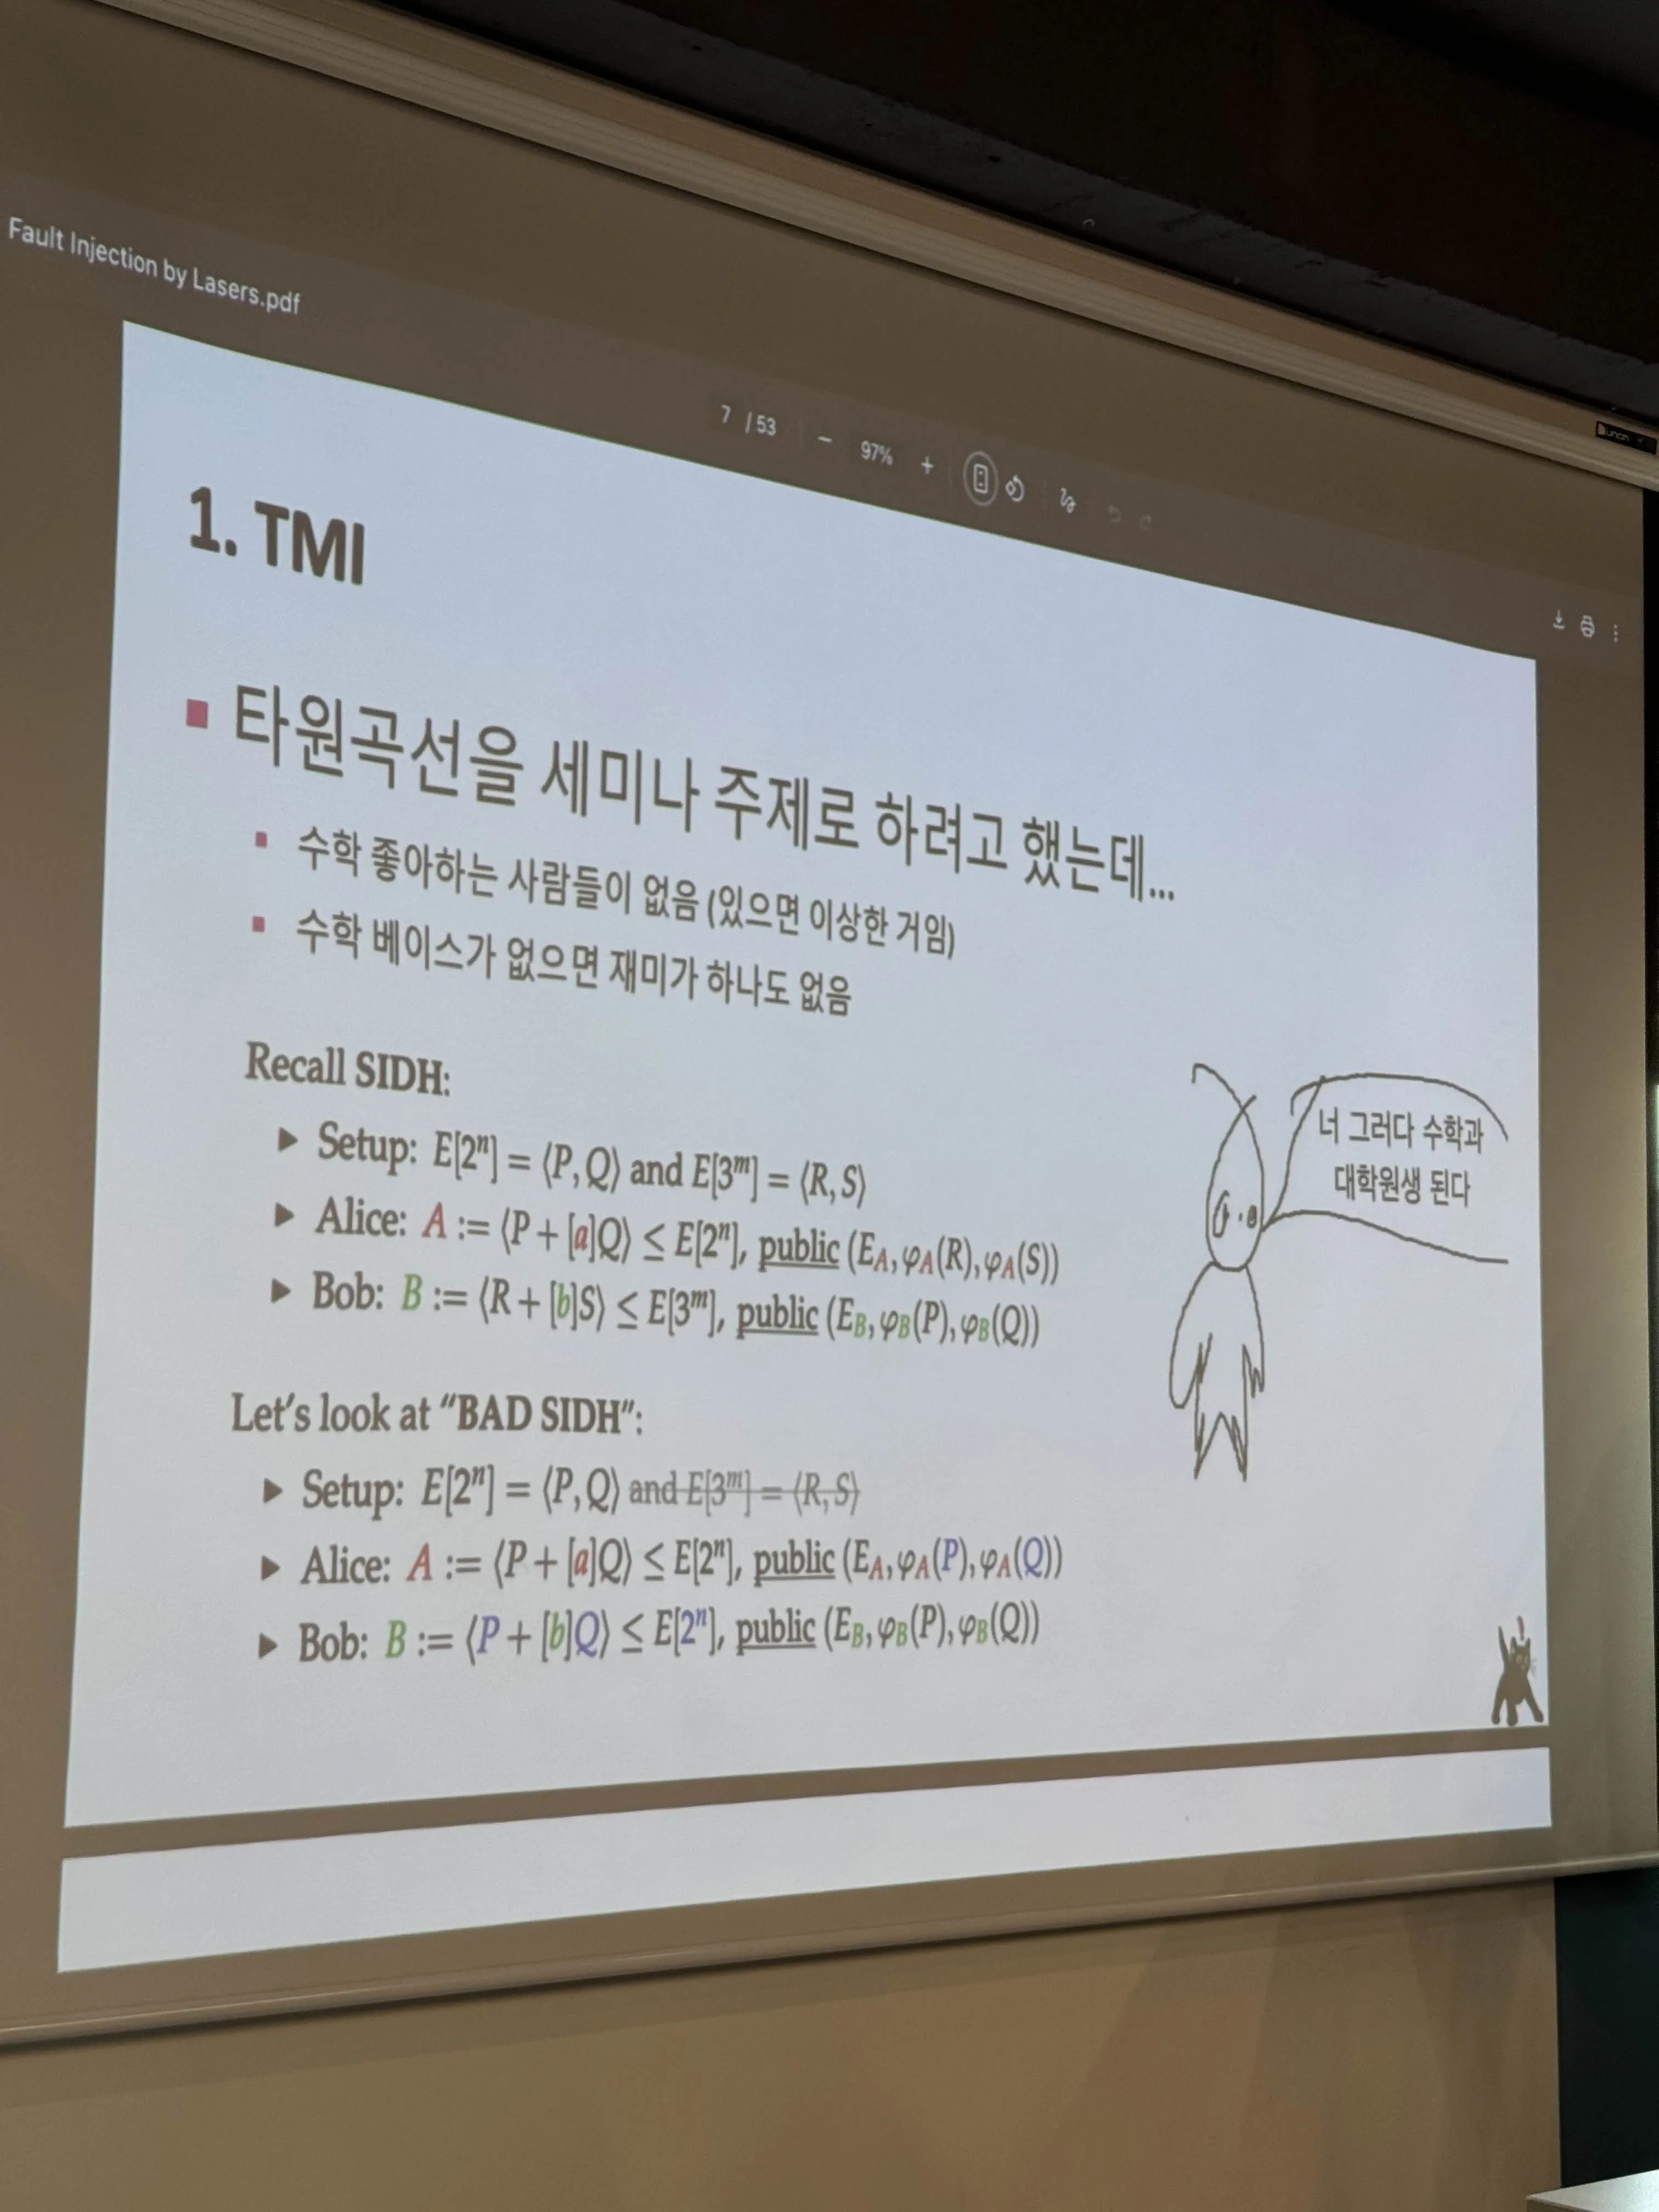
(From my presentation, “Introduction to Laser Fault Injection.” The slide reads: “I was going to talk about Elliptic Curves, but if you don’t have a mathematical background, it will be very boring, and you will end up in Graduate school majoring in mathematics, lol”)
Following a RubiyaLab seminar, I had a discussion with my great friend and cryptographer Donghyeon Kim (@1s0m0rph1sm). Our conversation on side-channel attacks and Correlation Power Analysis (CPA) led him to pose an interesting thought, “I’ve heard people say that you can define the Pearson Correlation Coefficient formally within the context of an space”
This gave me some spark and challenge to work on during my free time, which I encountered some good papers that talk about this, and also was able to revise my knowledge on basics of Quantum computation lol!
Introduction to Pearson Correlation in Euclidean Space
In statistics, the Pearson Correlation Coefficient (PCC) is a correlation coefficient that measures linear correlation between two sets of data.
It is the ratio between the covariance of two variables and the product of their standard deviations. It is essentially a normalized measurement of the covariance, such that the result always has a value between and .
For example if we have two discrete datasets and , the sample Pearson Correlation Coefficient (PCC) is given by:
The formula suggests geometric interpretation. We can define centered vectors in :
Here, and are treated as vectors in , and and are scalar multiples of the vector of ones. With the standard Euclidean inner product the PCC formula can be transformed into the cosine of the angle between these centered vectors:
This gives us some clear understanding using geometric foundation. But to generalize this concept from finite data points to continuous random variables, we have to change our perspective from finite-dimensional Euclidean space to an infinite-dimensional function space, which brings us to the Hilbert’s space.
Introduction to Hilbert’s space
A Hilbert space is a mathematical concept that generalizes the familiar notion of Euclidean space. It’s an inner product space, meaning that it’s a vector space where you can measure lengths and angles, and it’s also complete, which means all of its limit points exist within the space. This makes us able to bring topics such as geometric concepts. If we say in one paragraph, we can say that “Hilbert space is a complete complex vector space that has a scalar product”.
A Hilbert space, denoted as , is defined by two characteristics: being a vector space with an inner product, and completeness.
To explain this smoothly, I will bring some definitions from the book “Mathematics of Quantum Computing.”
Definition: A Hilbert Space is a
(i) complete complex vector space, that is,
(ii) with a (positive-definite) scalar product such that for all
and this scalar product induces a norm in which is complete. If the metric defined by the norm is not complete, then is instead known as an inner product space.
A subset which is a vector space and inherits the scalar product and the norm from is called a sub-Hilbert space or simply a subspace of .
space
IMPORTANT: To ease reading the formula we will substitute to , to .
is a great example of an infinite-dimensional Hilbert space. For our purposes, we consider the space of random variables with finite second moments (). For random variables defined over a continuous domain, the inner product is:
where is the probability density function.
The length of a vector is defined as :
Reconstructing Correlation in
Using the space, we can translate statistical concepts into functional analysis. Let and be two random variables in .
The covariance of and can be defined as:
Define the centered random variables, which are also elements of :
Note that and .
The covariance can now be expressed as an inner product of these centered variables:
For the variance,
So we will be able to get:
This reveals that the variance is the squared norm of the centered random variable:
So at the end of the day, the standard deviation is the norm of the centered variable:
Pearson Correlation as the Cosine in
We can now use this knowledge and glue it together. The Pearson Correlation Coefficient is the ratio of the covariance to the product of the standard deviations:
By substituting our Hilbert space representation for each term, we can get this elegant formulation:
This is the answer to the initial question. The Pearson Correlation Coefficient is defined in the Hilbert space as the cosine of the angle between the centered random variables and .
This is a well-known property that is an immediate and direct consequence of the Cauchy-Schwarz Inequality.
Huh????? What is this buckeroo Cauchy-Schwarz inequality? And why is this inequality an inherent property of all inner product spaces? Well, let’s get into it!
Intro to Cauchy-Schwarz Inequality
The Cauchy-Schwarz inequality states that for any two vectors and in an inner product space:
This isn’t an arbitrary rule; it arises directly from the axioms of the inner product itself, particularly the property of positive-definiteness, which states that the inner product of any vector with itself is non-negative ().
For example, consider any two vectors and a real scalar . Now form a new vector . Because of the axioms, we know its squared norm must be non-negative:
Expanding this using the properties of the inner product we saw before, we get:
We can rewrite this with the norm notation:
This is a quadratic polynomial in the variable . For this quadratic to always be non-negative, it can have at most one real root. This means its discriminant must be less than or equal to zero:
We can take the square root of both sides which gives us the Cauchy-Schwarz inequality:
This shows us that the inequality is not an external fact but a direct logical consequence of the geometric structure we imposed on the vector space. If we apply this to our centered random variables and , this guarantees: